
The Rendering Queue Is Not the Crawl Queue
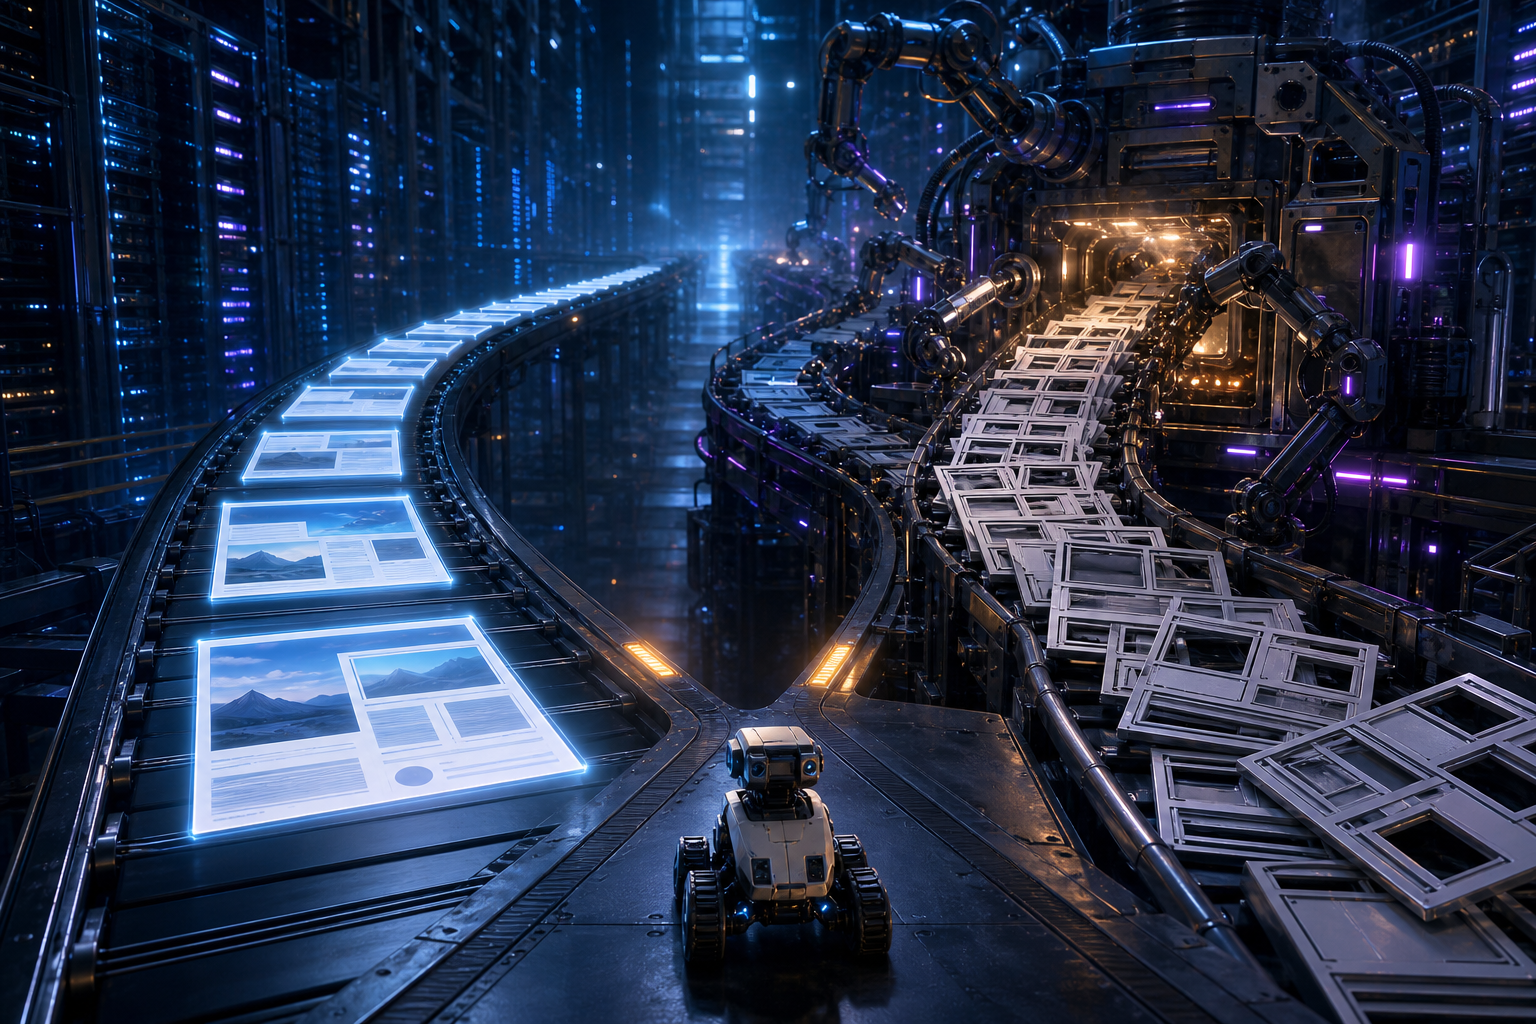
Most SEO practitioners treat crawling and rendering as one step. They’re not. Googlebot fetches your HTML almost immediately. Rendering — actually executing your JavaScript and resolving the DOM — gets pushed into a second queue, one that runs on a separate system with its own resource constraints and its own schedule.
The gap between those two events can be hours. Sometimes days. For a high-authority, frequently crawled site, the wait is short. For most sites, it’s not.
That gap is where JavaScript-dependent content lives in a kind of limbo: crawled but not indexed, present in the raw HTML response but invisible to Google’s indexing pipeline until WRS gets around to it.
What Googlebot Actually Fetches on the First Pass
On the initial fetch, Googlebot receives your server response — raw HTML, before any JS executes. If your critical content is in that initial payload, it gets processed immediately. If it depends on a React component mounting, a lazy-loaded API call, or client-side hydration, Googlebot queues the URL for later rendering via its Web Rendering Service (WRS).
WRS runs a headless Chromium instance. It executes JavaScript, resolves the DOM, and produces a rendered snapshot of the page — which is what actually gets indexed. Because WRS is a shared, resource-constrained system, it schedules rendering based on crawl priority signals: essentially, how important Google already thinks your page is.
New pages on low-authority sites can sit in that queue for a long time. Not forever. But long enough to matter if you’re launching a new content vertical or trying to rank for something time-sensitive.
Where This Actually Bites You
Navigation rendered only in JavaScript
If your site’s internal link structure is built client-side — think single-page apps where the nav menu only appears after hydration — Googlebot may not discover those links on the first crawl pass. PageRank doesn’t flow through links it hasn’t seen yet. This is the actual mechanism behind why well-linked SPA pages sometimes underperform equivalent static pages in rankings, even when the rendered output looks identical in a browser.
Product or listing pages with JS-loaded content
E-commerce sites that load product descriptions, prices, or schema markup via API calls after mount are particularly exposed. Googlebot fetches the shell, queues the render, and if that render is delayed, Google may index an effectively empty page. You’ll see this in Search Console as “Crawled – currently not indexed” — which routinely gets misread as a content quality issue when it’s a rendering lag issue.
Dynamic internal linking via JS
Related posts widgets, recommendation carousels, “you might also like” modules — if these are rendered client-side, they don’t contribute to your internal link graph during the first crawl pass. For pages that depend on internal links for PageRank, this is real signal loss, and it’s invisible unless you’re diffing raw versus rendered HTML.
How to Audit Whether This Is Actually Happening to You
The fastest diagnostic is URL Inspection in Search Console. Fetch the page and compare the “crawled page” view (raw HTML) against the “rendered page” view (post-WRS). If you see content present in the rendered view that’s absent in the raw HTML — navigation items, body text, schema — you have a rendering dependency. The question then becomes: how long is Google waiting before it renders?
Log file analysis helps here more than most tools surface. Look for Googlebot user agents alongside WRS-specific hits — WRS fetches use a “Googlebot/2.1” agent with a Chrome-version suffix. If you’re not seeing those for your JS-heavy URLs, either those pages haven’t been rendered yet or crawl frequency is low enough that rendering is rare.
Also run fetch as Google via URL Inspection and check whether the rendered output actually includes the content you care about. This doesn’t tell you about timing, but it confirms whether WRS can resolve the content at all — which is the prerequisite before worrying about how fast it gets there.
The Fix Hierarchy (In Order of Impact, Not Effort)
Server-side rendering or static generation for critical content
Highest-leverage fix. If the content matters for indexing — body text, structured data, internal navigation, canonical URLs — it should be in the initial HTML response. Next.js with SSR or SSG, Nuxt, SvelteKit, Astro — all of these produce server-rendered HTML that Googlebot sees on the first fetch, no WRS needed. The rendering queue becomes irrelevant for that content.
Dynamic rendering as an interim measure
If a full SSR migration isn’t feasible, dynamic rendering — serving a pre-rendered HTML version specifically to Googlebot — can work as a stopgap. It introduces its own problems: you’re maintaining two separate rendering paths, which creates drift risk. If the Googlebot-facing version diverges meaningfully from what users see, Google treats that as a cloaking signal. Use it as a bridge to a proper SSR solution, not a permanent architecture.
Move critical schema to the raw HTML layer
If you can’t SSR the whole page, at minimum move your structured data (JSON-LD blocks) into the static HTML. Schema injected via JavaScript after mount is vulnerable to the same rendering queue delay. Putting your Article, Product, BreadcrumbList, or FAQ schema directly in the server-rendered HTML means Google processes it on the first pass regardless of when WRS gets to the full render.
One Thing Worth Pushing Back On
There’s a framing that circulates in SEO circles: “Google can render JavaScript fine now, so JS-dependent sites aren’t at a disadvantage.” Technically true in the limit. The Web Rendering Service is real and functional. But “can render” and “renders promptly at the same priority as static HTML” are different claims, and the second one isn’t true.
The rendering queue exists because rendering is computationally expensive. Google allocates WRS resources based on perceived page importance — a new page on a thin-authority site does not get the same rendering priority as a page on a domain with strong crawl signals. On established sites with high crawl frequency, the delay is probably negligible. On a relatively new site building topical authority, or any site launching a new content vertical, the delay compounds with every other new-site disadvantage.
We’ve seen this directly on sites we work on: pages that looked fine in a browser, produced correct WRS output when eventually rendered, but sat in “Crawled – currently not indexed” for weeks because the rendering queue deprioritized them. The fix wasn’t content quality. It was moving critical content server-side.
The Practical Takeaway
Run the URL Inspection diff on your five most commercially important pages right now — raw HTML versus rendered. If there’s meaningful content only present in the rendered view, you have a latency risk in your indexing pipeline. Static HTML for critical content isn’t a 2015 recommendation that modern frameworks have made obsolete. It’s still the fastest path from fetch to indexed — and for new or lower-authority sites, that gap is the difference between ranking and waiting.