
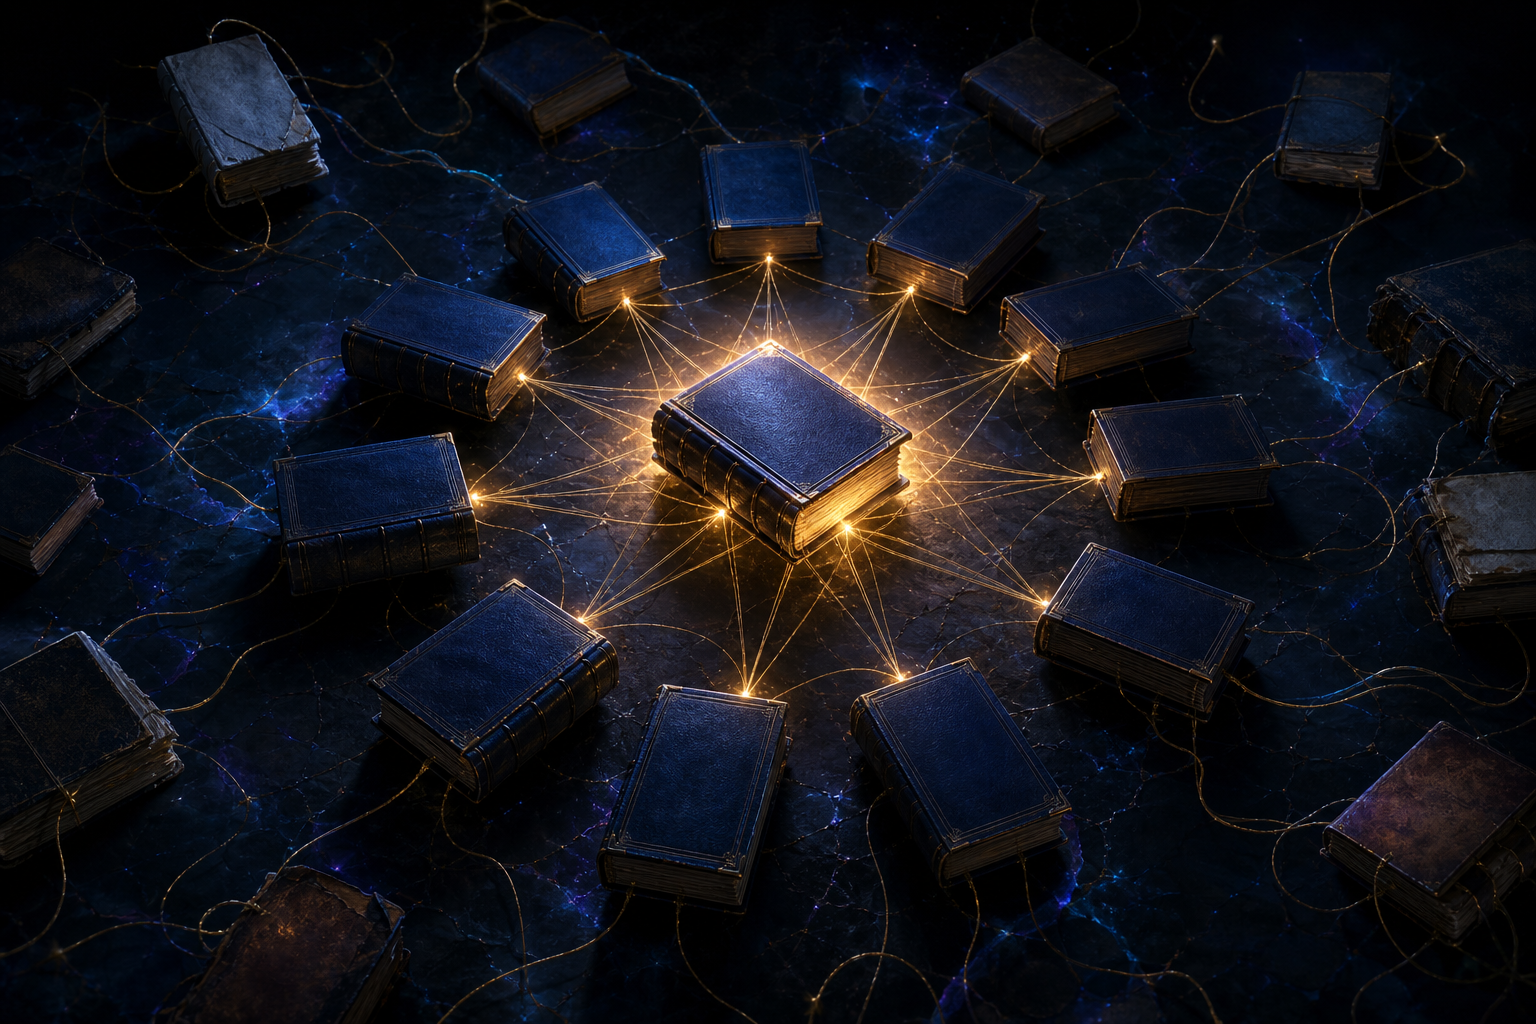
Most hub-and-spoke content models are built on a flawed assumption: that linking a cluster of supporting pages to a pillar automatically transfers topical authority upward. It doesn’t. Not reliably. Understanding why requires thinking about how Google measures the semantic relationship between two documents — not just whether a link exists between them.
The Link Is Not the Signal. The Semantic Distance Is.
Google’s internal document representations aren’t about which pages link to which. They’re about how conceptually close two documents are in the same vector space. Two pages can be hard-linked and semantically distant. A supporting page about “how to clean hiking boots” linking up to a pillar on “hiking gear” contributes almost nothing to the pillar’s authority on tent selection — the semantic overlap is narrow and the entities involved are mostly orthogonal.
The mechanism that matters here is what practitioners loosely call semantic proximity: the degree to which two documents co-activate the same entity clusters, subtopics, and lexical neighborhoods when Google processes them. A supporting page with high semantic proximity to its pillar reinforces the pillar’s topical signal. A supporting page with low proximity effectively exists in isolation, regardless of how tightly you’ve linked them structurally.
This is why you can build a cluster of 30 articles, link them all to a pillar, and watch the pillar fail to rank against a competitor running 8 pages that actually share deep topical overlap with their main piece.
What High Semantic Proximity Actually Looks Like
Proximity isn’t about keyword repetition. You’re not trying to stuff the same terms into every cluster page. It’s about shared entity coverage and subtopic intersection.
Take a pillar targeting “enterprise password management.” A high-proximity supporting page might cover LDAP integration challenges with password vaults — because that page activates the same entity clusters (Active Directory, SAML, privileged access management, Zero Trust) the pillar needs to demonstrate authority over. A low-proximity page might cover “how to create a strong password” — technically adjacent, but sitting in a completely different entity neighborhood: user behavior, consumer security hygiene, password length heuristics. Linking the second page to the pillar doesn’t pull those entity clusters into the pillar’s orbit. Google can tell the difference.
High-proximity supporting pages typically share:
- Named entities that also appear in the pillar — not just the topic category, but the specific products, standards, and organizations
- Subtopic coverage that fills gaps in the pillar rather than retreating to a more general or consumer-facing framing
- Similar implied query intent: the reader who would benefit from the supporting page is recognizably the same reader the pillar serves
Where Most Content Clusters Break Down
The failure mode we see most often is topical drift by category. Someone plans a cluster around a broad head term, then maps supporting pages by asking “what subtopics exist under this category?” instead of “what specific questions does my exact target reader have that require a dedicated page?”
The first approach generates a long list of tangentially related articles. The second generates a tight cluster where every page shares a common entity core.
The practical consequence: pillar pages surrounded by drifted clusters tend to hit a ranking ceiling that’s hard to break through, because Google’s quality signals for the page’s topical neighborhood are mixed. The pillar signals “enterprise password management” but two-thirds of its cluster signals “password hygiene for individuals” or “general cybersecurity tips.” The topical peer group Google assigns to the pillar gets contaminated.
We ran into a version of this while working through keyword cannibalization between two competing content properties. The underlying issue wasn’t just that two pages targeted the same keyword — it was that the supporting content around each page pulled in different topical directions, fragmenting the entity signal instead of concentrating it.
How to Audit Semantic Proximity in Your Own Cluster
You don’t need a proprietary tool. The diagnostic is conceptual first, then mechanical.
Step 1: Extract the core entity list from your pillar. Not keywords — entities. Named products, organizations, standards, processes, roles. An enterprise password management pillar should yield 15–25 specific entities it covers or implies coverage of.
Step 2: Score each supporting page against that entity list. How many of those entities appear as meaningful coverage (not passing mentions) in each supporting page? A page hitting 8 or more is probably high proximity. A page hitting 2 is probably drifted.
Step 3: Check the implied reader. Read the first paragraph of each supporting page without looking at where it links. Could you tell from that paragraph alone that this reader is the same person who needs the pillar? If the answer is clearly no, you have a proximity problem.
The mechanical version involves comparing TF-IDF vectors or embedding distances between documents — Screaming Frog with custom extraction or a Python cosine similarity script can approximate this. But the conceptual audit gets you 80% of the way there faster.
What to Do With Low-Proximity Pages
Don’t reflexively delete them. Low-proximity supporting pages aren’t necessarily bad pages — they might rank fine independently for their own queries. The problem is linking them upward to a pillar they don’t reinforce. That internal link doesn’t help the pillar, and it may be broadening Google’s sense of what the pillar is actually about in ways that hurt you.
In order of what I’d actually recommend:
- Re-cluster them to a different pillar if one exists or should. A page about consumer password habits belongs under a different topical hub than enterprise password management.
- Delink them from the pillar without removing the page. Let it live independently or link it to a genuinely relevant hub. Stop letting it dilute the pillar’s entity signal.
- Rebuild the page with the pillar’s entity core in mind, if the topic genuinely belongs in the cluster but the execution drifted.
Deletion is right only when the page has no independent ranking value, no backlinks worth preserving, and rebuilding isn’t worth the effort. That’s a narrower set of cases than most audits treat it as.
One Caveat Worth Being Honest About
Google doesn’t publish a “semantic proximity score” — the term is a practitioner construct for a real underlying mechanism, not a documented system with a named output. What’s documented through patents, research papers, and quality rater guidelines is that Google builds dense document representations well beyond keyword matching, and that topical coherence at the site and cluster level influences how individual pages are evaluated. The model described here is the most accurate framing of that behavior based on what’s publicly known. It’s still a model, not a verified read of Google’s actual weights.
Treat it as a diagnostic frame, not an engineering spec.
The Practical Takeaway
Before you add another supporting page to a cluster, ask one question: does this page share at least half of the core entities my pillar covers? If not, you’re not building topical authority — you’re building topical noise. Fix the pages you already have before scaling a cluster that’s working against itself.